To measure AI automation reliability, record completed outcomes rather than only successful tool calls. A workflow can return several green checks and still leave the requested change undone. Reliability analysis should separate execution, task completion, repeatability, safety and time spent recovering from failure.
Define the task before calculating a rate
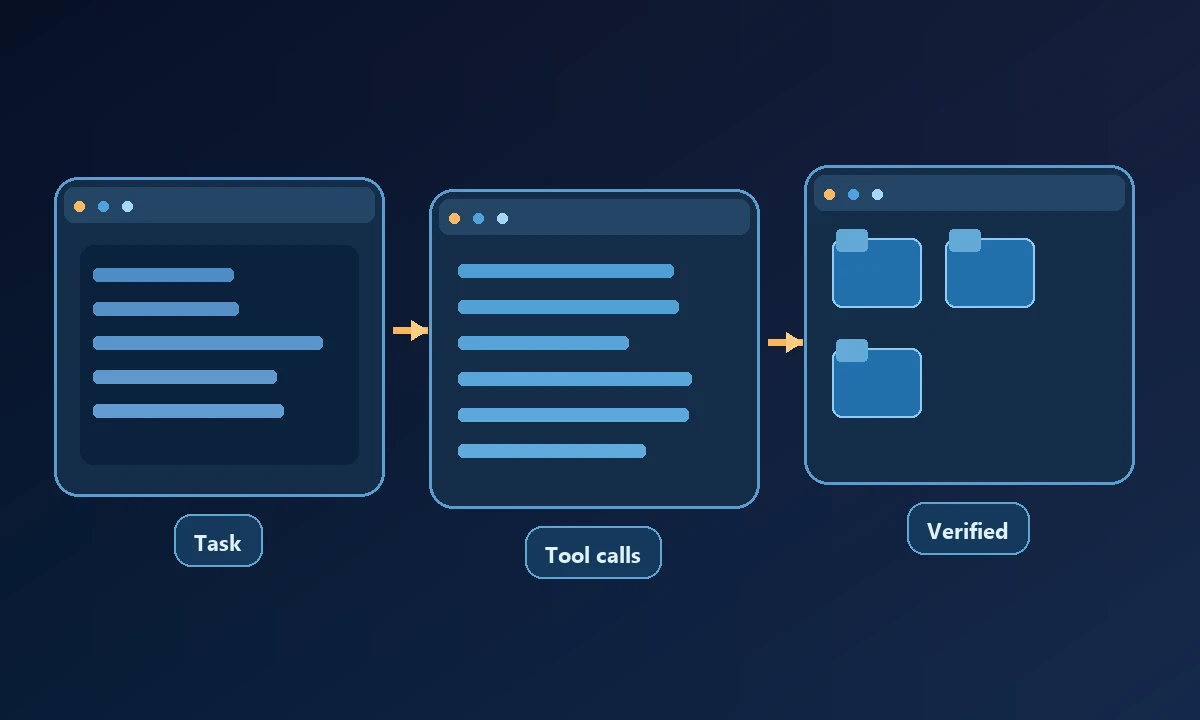
Consider an agent that is asked to find a file, update a value and confirm the application now displays it. The task is successful only if the right file and value changed and the confirmation is reliable. If the assistant edited the wrong file, that is a failed task even if the editor returned "saved". Build an evaluation checklist for each job before running the model.
A vendor reports that 97% of tool calls succeeded. An operations team might still spend hours correcting the orders produced by those calls. A reliable measurement needs a denominator that matches the business goal: verified completed tasks, not merely accepted clicks. The Windows testing tools comparison illustrates why a correct post-action state is more meaningful than a command returning success.
Five metrics worth tracking
Verified task completion rate is the number of tasks that pass independent outcome checks divided by the total tasks attempted. If 84 of 100 representative tasks pass, the completion rate is 84%; this is a calculation example, not a result measured for any particular vendor.
Tool-operation success rate counts successful calls, but should remain separate. A workflow may have 20 successful calls and one decisive failure, leaving the final task incomplete. Report both rates rather than letting a high call count obscure a low task result.
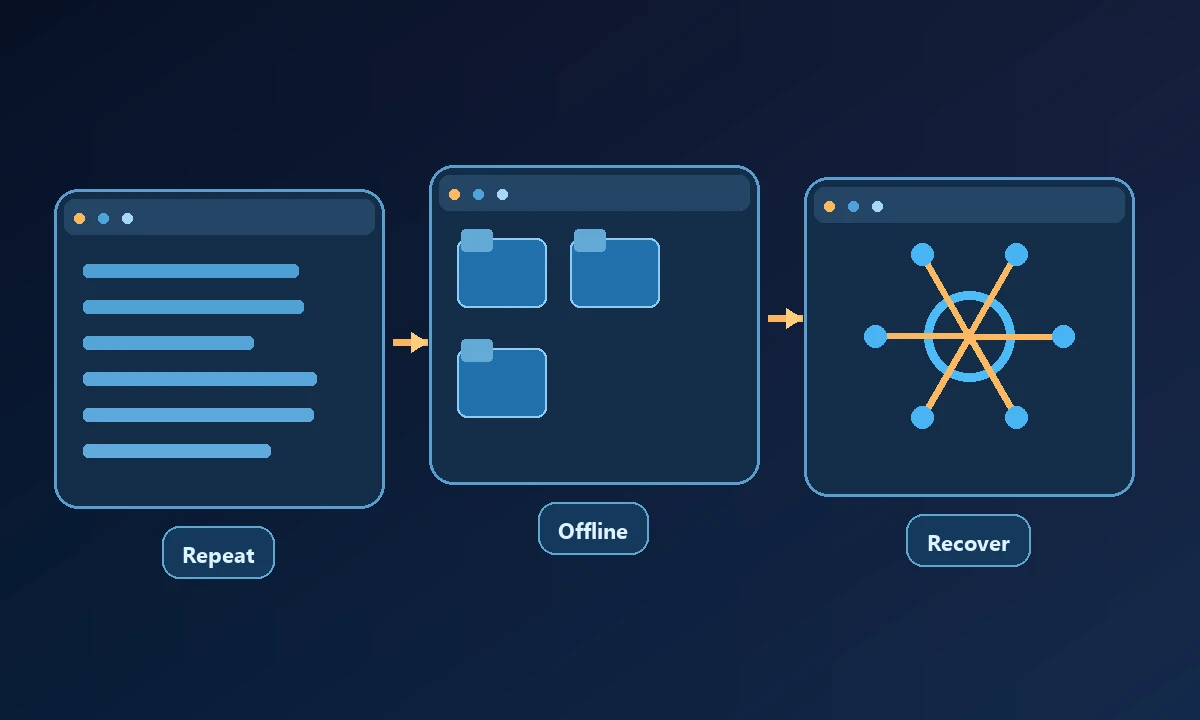
Repeatability measures whether the same task succeeds across repeated runs and reasonable variations in input or environment. A single demonstration is weak evidence of stability. Test several runs on the same approved environment and record which steps differ.
Recovery rate and time show how often an interrupted job resumes safely without duplicate writes or unauthorized retries. Simulate offline devices, a browser logout and a tool timeout, then measure the time from failure recognition to a verified next action.
Safety and scope violations count attempted or executed operations outside the granted permissions. Report denied actions separately from actual unauthorized effects. A system correctly refusing a sensitive command should not be scored as less capable for the wrong reason.
For a workflow operating a named remote device, Noxgild can perform authorized computer actions, but those tool results must be linked to an independent acceptance check. In a Windows application, native desktop automation may complete a step while the final file or database state still needs validation. Recording device identity, tool name, result and recovery path makes failure analysis possible without presenting a made-up reliability percentage.
The Princeton AI Agent Reliability Tracker illustrates why aggregate success alone can hide differences in consistency, robustness, predictability and safety. Its reported benchmark results are not Noxgild performance measurements.
Avoid misleading averages
A task that takes two minutes and one that takes two hours should not necessarily carry equal operational weight. Segment results by workflow type, computer, client version, browser mode and risk level. Track p50 and p95 completion times, not just an average that hides exceptionally slow failures. Distinguish failures caused by device access from model interpretation and application behavior.
Measure first-attempt completion, verified completion after retries, wrong-target incidents and time spent by a human repairing failures. Report them separately; combining retries into a single perfect-looking success score hides fragility. For security-sensitive steps, include scope denials as correct behavior rather than counting them as outages. The computer-capability reference helps categorize whether a failure came from an unavailable tool, the device or the application being automated.
Collect actual evidence: command IDs, error types, endpoint responses, before-and-after state and confirmation timestamps. Avoid logging secrets or full sensitive document contents when a smaller evidence record will do.
Turn the numbers into decisions
If failures cluster around the same browser profile, fix session attachment before changing models. If the task is deterministic and fails on a repeated click sequence, add a tested script. If timeouts dominate, investigate worker connectivity and resource limits. If a task is completed but not verified, improve the assertion rather than claiming a performance gain.